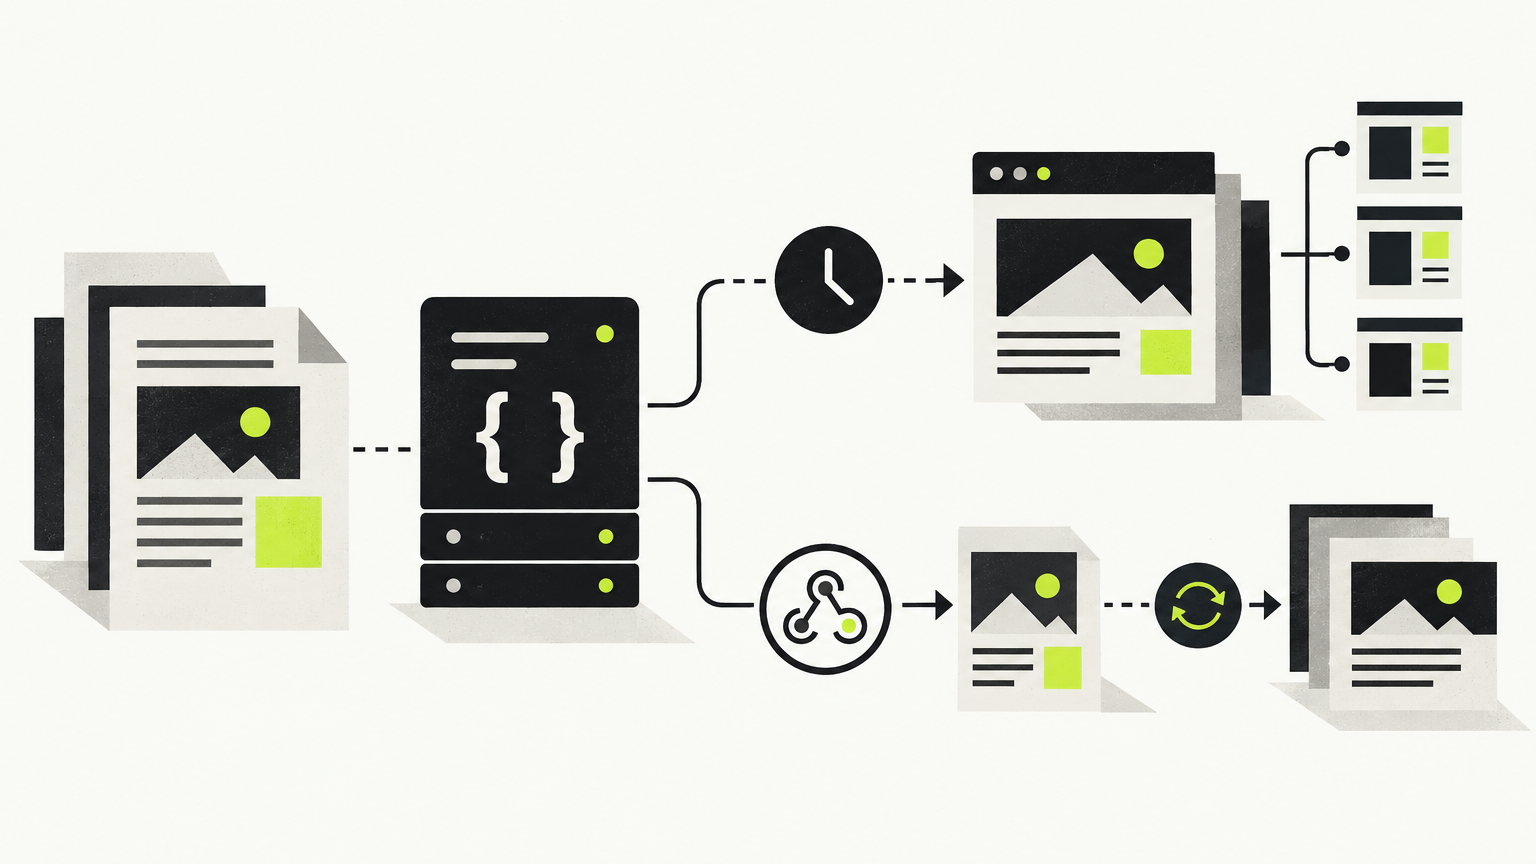
If you run a coded frontend — Next.js, Astro, Nuxt, SvelteKit, headless WordPress — automated content delivery comes down to two patterns, and it is worth picking one deliberately rather than bolting both on later.
Pattern A (pull): your frontend requests articles as JSON from a content API on a schedule — at build time, on a cron, or on a time-based revalidation cycle.
Pattern B (push): the content source calls your endpoint at publish time with the article payload (or a change notification), and your handler revalidates only the affected routes.
Everything else — canonicals, sitemaps, lastmod dates, structured data — sits in the seam between the API and the rendering layer. In a decoupled setup, the backend serves JSON and your application produces the HTML, so anything that has to appear in the <head> or in a sitemap file is your application's responsibility. The WordPress REST API, for example, is explicitly described as an interface for sending and receiving data as JSON so that applications can "bring your WordPress content into completely separate applications" (WordPress REST API Handbook). It returns fields such as title, content, excerpt, slug, status, date, modified and link (WordPress REST API: Posts) — data, not rendered markup.
Pattern A — REST pull on a build, cron, or revalidation cycle
The pull model is the simplest thing that works. You fetch a list endpoint, render routes from it, and let a timer decide how stale a page may get.
In the Next.js App Router this is the revalidate segment config plus generateStaticParams: pages are prerendered at build, served from cache, and after the revalidation window the next request triggers a background regeneration while the cached page is still served (Next.js ISR docs). Next.js explicitly recommends a high revalidation time — "1 hour instead of 1 second" — and says that if you need more precision you should consider on-demand revalidation instead (Next.js).
Two caveats worth knowing before you commit: ISR is only supported on the Node.js runtime and is not supported when creating a static export, and if any fetch on the route has a revalidate time of 0 or an explicit no-store, the route is dynamically rendered (Next.js).
On the source side, a REST list endpoint usually gives you the pagination and filtering you need for a reconciliation job. The WordPress posts endpoint, for instance, supports page, per_page, after, modified_after, status, slug and ordering parameters (WordPress REST API: Posts) — enough to ask "what changed since yesterday?" without walking the whole archive.
Pull is a good default when publishing is predictable, when you don't want to operate an inbound endpoint, and when a delay of minutes-to-an-hour before a new post appears costs you nothing.
Pattern B — webhook push at publish time
The push model inverts control: publishing fires an HTTP POST at a URL you own, and your handler decides what to invalidate.
This pattern is documented by API providers outside the CMS world. monday.com applies the idea to board events: you subscribe to events and get notified by an HTTP or HTTPS POST request to a specified URL with the event information as a payload (monday.com).
On the frontend side, Next.js exposes revalidatePath for whole routes and revalidateTag for tagged data; revalidateTag "invalidates data with specific tags across all pages that use those tags, while revalidatePath invalidates specific page or layout paths" (Next.js revalidateTag). Its API reference is specific about the webhook case: when invalidation comes from outside a Server Action — "a webhook or another service calling a Route Handler" — pass { expire: 0 } so the data expires immediately rather than being served stale (Next.js).
Push buys you latency. It also hands you three problems that pull doesn't have: retries, ordering, and duplicates.
Trade-offs at a glance
| Dimension | REST pull (build / cron / ISR) | Webhook push |
|---|---|---|
| Freshness | Bounded by your revalidation window | Near-publish, if delivery succeeds |
| Who owns failure | You (a failed fetch just retries next cycle) | You and the sender (retries, redelivery) |
| Cost profile | Scales with schedule frequency, not publish volume | Scales with publish events |
| Blast radius per publish | Whole build, or every route on its timer | Only the routes you choose to revalidate |
| Ordering | Irrelevant — you read current state | Not guaranteed by every provider; check your sender's documentation |
| Hidden failure mode | Stale lastmod, silently old pages |
Missed delivery = a page that never appears |
| Debuggability | Re-run the fetch | Depends on the sender's delivery log |
A pragmatic combination: webhook for latency, scheduled pull as the reconciliation loop. The cron job is your safety net for anything the webhook dropped.
Hardening the receiving endpoint
Providers differ enormously here, so read your sender's spec rather than assuming. One documented example shows the shape:
- Verification. monday.com uses a challenge/response handshake at registration — it sends "a JSON POST body containing a randomly generated token as a
challengefield" that you must return in your response — and some webhook requests contain a JWT in theAuthorizationheader that you can verify against the app's Signing Secret (monday.com). - Retry windows. monday.com retries "once a minute for 30 minutes" (monday.com). A sender's retry window determines how long an outage can last before you lose an article permanently.
One more rule that generalises well: be idempotent. Because senders retry failed deliveries, the same article can legitimately arrive twice; key on a stable article or event ID so a replay updates rather than duplicates.
One more Next.js-specific trap: with multiple instances, the default file-system cache is per-instance, so on-demand revalidation "only invalidates the instance that receives the call" — you need a shared custom cache handler to coordinate (Next.js). Also, path rewrites in Proxy aren't applied to on-demand ISR requests, so revalidate the exact path (/post/1, not a rewritten /post-1) (Next.js).
The SEO seam: fields nothing supplies by default
No rendering layer invents metadata for you, and a JSON API returns whatever fields the content model defines. A WordPress post object, for example, carries slug, title, content, excerpt, date, modified, status and arbitrary meta fields (WordPress REST API: Posts) — the raw material for a <head>, but not the <head> itself.
A sensible payload contract for an automated blog, written as a checklist rather than a claim about any particular product:
- a unique, validated slug (the WordPress schema describes
slugas "an alphanumeric identifier for the post unique to its type" — WordPress); - a title and description field for the
<head>, distinct from the on-page headline if you want to tune them separately; - a canonical URL;
- an Open Graph image reference, kept separate from the cover image if social crops differ from layout crops;
- an indexing flag for thin or utility pages;
- published and modified timestamps — the WordPress API exposes both
date/date_gmtandmodified/modified_gmt(WordPress); - author references.
One practical implementation note: request the whole head in a single article fetch. If you assemble it from several calls, a field can quietly disappear from one response and you ship pages with half a <head> and no error anywhere.
Also model slug history. If an automated publisher ever changes a URL, you need a redirect, and in a decoupled setup nothing in the content API performs that redirect for you — your application or your edge layer has to.
Sitemaps and lastmod should regenerate on publish, not on rebuild
The most invisible failure is a sitemap whose lastmod is frozen at the last full deploy. A timestamp that tracks your deploy schedule rather than your edits describes when you shipped, not when the page changed.
The fix is to drive sitemap lastmod and JSON-LD dateModified from the same modified timestamp your revalidation fires on, so all three stay aligned automatically. The WordPress API, for instance, exposes modified and modified_gmt alongside date/date_gmt (WordPress).
Indexing hygiene for automated pipelines
Automation multiplies mistakes quickly, so put guardrails in before you turn it on:
- Point preview and staging environments at a separate content feed, and keep preview routes out of the index. Note that the WordPress REST API applies "the same authentication restrictions" as the site itself — public content is publicly accessible, while drafts and private content require authentication (WordPress REST API Handbook), so rendering drafts is a deliberate authenticated integration, not a default.
- Decide one canonical URL per article if the same content also lands on another channel, and list only that URL in the sitemap.
- Log every delivery with its article ID and resulting revalidation, so a missing page is a lookup rather than an investigation.
Headless WordPress as a middle path
If your editors already live in WordPress, you can keep it as the backend and replace only the theme layer with a framework frontend. WordPress documents the REST API as the structured way to "get data in and out of WordPress" for client-side JavaScript applications or standalone programs in languages other than PHP (WordPress REST API Handbook), and the posts reference gives you the exact routes: GET /wp/v2/posts for the collection, GET /wp/v2/posts/<id> for a single record, plus POST and DELETE for writes (WordPress).
Be honest about the trade: you keep the editorial UI, but you now operate a second application with its own build, deploy and hosting, and every template-level SEO behaviour that a theme used to handle becomes code you own. WordPress itself is blunt that this is optional — "you should not feel pressured to use the REST API if your site is already working the way you expect," and "you do not need to use the REST API to build a WordPress theme or plugin" (WordPress REST API Handbook). If a conventional coupled CMS already publishes what you need, that is the cheaper answer; decoupling earns its cost only when you actually need the separate frontend.
REST or GraphQL for article retrieval?
Pick based on the shape of your page, not on fashion. REST maps cleanly when a page corresponds to a single resource: one article request returns slug, body and metadata, and a list endpoint with pagination parameters covers the feed — the WordPress posts endpoint's page, per_page and modified_after arguments are a good illustration (WordPress). A query language becomes more attractive when a single page stitches together several content types and you want to avoid multiple round trips or over-fetching. For a straightforward article feed, REST plus pagination is usually enough. Whichever you choose, the SEO seam described above is identical.
If you want the writing automated too
Disclosure: this blog is published by PilotScribe, so treat this section as a vendor description rather than an independent recommendation.
If the bottleneck isn't the wiring but producing the articles, PilotScribe states in its documentation that it can publish to an existing CMS, to a hosted blog, or — for coded sites — through a headless Content API where you "pull articles via JSON and render them on your own site, your own way," as well as a webhook option that delivers "each article as signed JSON on your own endpoint" (PilotScribe docs). Those are the company's own descriptions; check the documentation for the endpoint, authentication and payload details before you design your content model around it. The same evaluation applies as to any other source: whatever supplies the JSON, you still own the <head>, the sitemap and the redirects.
A canary test before you go live
This is a suggested procedure, not a report of a test we ran on your stack. Run it once, with a single throwaway article, in production:
- Publish the canary and confirm the payload arrives — or that the pull endpoint returns it.
- Verify the signature or challenge on the raw, unmodified body. If verification fails, check whether middleware is rewriting the body before your handler sees it.
- Replay the same delivery and confirm you get one article, not two.
- Confirm the target route revalidated. In Next.js you can read the
x-nextjs-cacheresponse header, whose values areHIT,STALE,MISSorREVALIDATED(Next.js). - Check the rendered
<head>in view-source, not devtools: title, meta description, canonical, OG image, JSON-LD. - Check the sitemap contains the new URL, as a fully-qualified absolute URL, with a
lastmodmatching the publish time. - Simulate a failure — return a 500 from your endpoint once and confirm the sender retries within the window its documentation specifies.
- Only then submit or resubmit the sitemap.
FAQ
Do I need a webhook if I already rebuild nightly?
Not necessarily. If a post appearing up to a day late is acceptable, a scheduled pull is less machinery to operate. The cost shows up in lastmod accuracy: if the timestamp is generated at build time it reflects the deploy, not the edit. Derive it from the content's modified field instead.
What happens if a webhook delivery is missed entirely?
The article silently never exists on your site. That's why a low-frequency reconciliation pull — fetch everything modified in the last N days and revalidate anything missing — is worth the extra job. A modified_after-style filter makes it cheap (WordPress).
Should the webhook carry the full article or just an ID? Either works. A full payload lets you render without a second call; an ID-only notification means you always read current state and never act on a stale body, which helps when ordering isn't guaranteed.
Does going headless improve SEO by itself?
No. A content API returns JSON; sitemaps, canonicals, redirects and structured data are produced by your application. A team that skips that work can ship a fast site with a worse <head> than the coupled CMS it replaced.